 By Tsuky
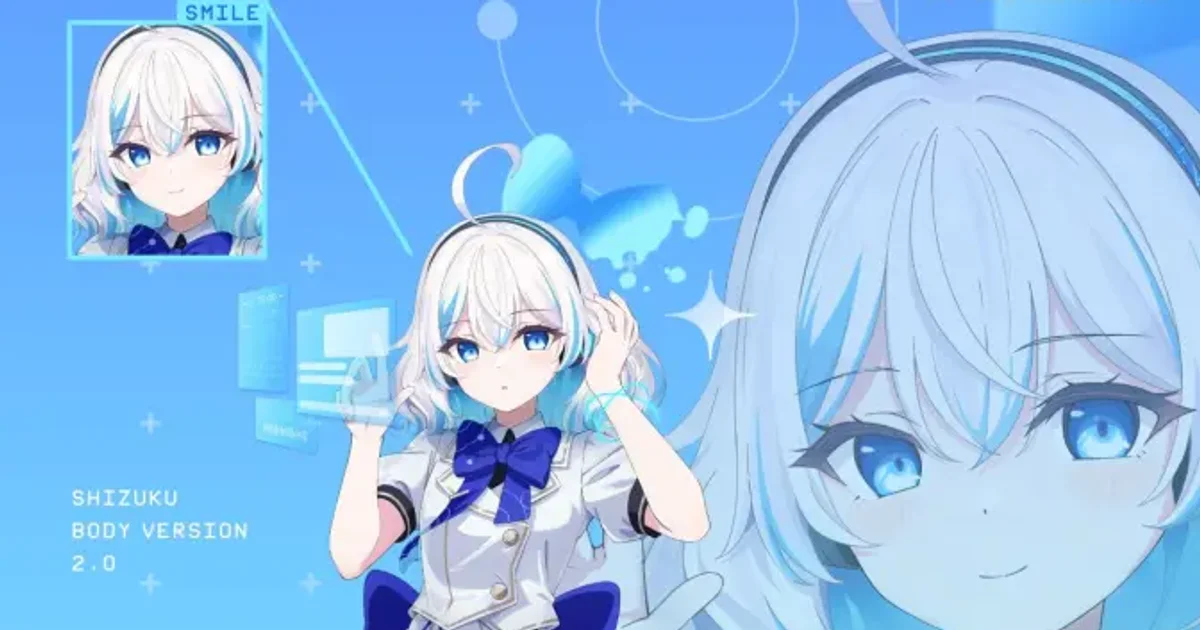
Most people do not conduct conversations as neatly separated sequences of questions and answers. They pause, interrupt, acknowledge what they hear and occasionally speak at the same time. Traditional voice interfaces can struggle with those behaviors. A short acknowledgment may cause an assistant to stop talking. An interruption can arrive while the system is still producing an answer. Even a simple pause may be misinterpreted as the end of a question. Shizuku AI is developing a different kind of voice interaction around these problems. Its Shizuku-Duplex model is designed specifically for Japanese conversations in which listening and speaking can happen simultaneously.
Full-duplex means listening does not stop when speaking begins
Many conventional voice systems use a sequential architecture. They detect the end of an utterance, convert speech to text, process the request through a language model and synthesize the reply. The sequence works well for simple commands. However, it often creates a rigid division between speaking and listening.
A full-duplex system can continue processing incoming audio while producing outgoing speech. This changes the interaction. The assistant can acknowledge a user's words without waiting for the entire sentence. It can respond to an interruption while delivering an answer. It can also recognize that a short sound may be a conversational acknowledgment rather than a request to stop.
These decisions require more than a fast speech synthesizer. The model must determine who is speaking, whether an utterance is relevant and when its own response should begin or end. Shizuku-Duplex places those decisions inside the real-time conversation architecture.
The 80 ms number is an inference interval
Shizuku AI describes the model as operating in 80-millisecond cycles, or ticks. Each cycle processes incoming audio information and contributes to the model's output. The computation for a cycle must fit within the available time to maintain real-time operation. The developers report using TensorRT and optimized Triton kernels to achieve that processing cadence.
This is an important technical result, but it is frequently misunderstood. The model does not necessarily produce a complete answer 80 milliseconds after a question. Understanding an utterance, selecting a response and generating speech can require many consecutive cycles. External tasks, including web searches, may take considerably longer.
The 80 ms figure therefore describes the system's internal operating rhythm rather than end-to-end user-perceived latency. Actual response timing also depends on processing conditions, networking and the application through which the model is accessed.
The median response delay is closer to 570 ms
Shizuku AI provides a separate measurement for the time between the end of a user's utterance and the beginning of a response. Its reported median is 0.57 seconds. GPT-Live-1 achieved 0.53 seconds in the comparison published by the researchers. That places the two systems close together on this metric.
The same tests report 1.27 seconds for Gemini 3.8 Live and 1.61 seconds for GPT-Realtime-2.1. However, the methodology is not identical across those systems. Shizuku-Duplex and GPT-Live were measured using server-side recordings that exclude network round-trip time. The measurements for Gemini Live and GPT-Realtime included network delay through a different recording method.
The results are useful, but they should not be interpreted as a perfectly controlled ranking of real-world service latency. The measured differences partly reflect the conditions under which each system was evaluated. Independent testing under a consistent methodology would provide stronger evidence of relative speed.
Shizuku-Duplex performs well when users interrupt
One of the more convincing results concerns interruption handling. An assistant needs to recognize when someone is attempting to stop or redirect its response. The Shizuku AI evaluation reports that its model stopped speaking within two seconds in 89% of interruption scenarios. GPT-Live-1 reached 82% under the same published comparison.
Another task tests whether the model can keep talking when the user makes a short acknowledgment. Shizuku-Duplex continued appropriately in 95% of those scenarios. This distinction matters. An interruption should often cause the assistant to yield the floor. A brief acknowledgment may instead indicate that the user is listening and wants it to continue.
Incorrectly treating both signals as equivalent creates unnatural conversations. The published results suggest that Shizuku-Duplex has learned useful distinctions between these situations. They do not establish flawless behavior, but they demonstrate progress beyond simple voice activity detection.
Background speech remains a major weakness
The same evaluation exposes significant limitations. When a user speaks to someone else, Shizuku-Duplex responds in 83% of the tested cases. In scenarios involving background speech, its unwanted response rate reaches 75%.
These are undesirable results. An assistant intended to remain available throughout everyday activities must distinguish speech directed toward it from unrelated conversation. Otherwise, it risks interrupting people who never intended to address it.
The results demonstrate that managing interruptions successfully is not equivalent to understanding every conversational context. A system can be responsive while still intervening too often. For always-listening companions, learning when to remain silent may be as important as reducing the delay before speaking.
Two models separate conversation from difficult tasks
Shizuku-Duplex uses a two-part architecture. The interaction model handles the immediate conversation. A background model processes tasks that require additional reasoning or external tools. This arrangement allows the foreground system to continue speaking while the background component works.
The developers illustrate this with a travel-planning request. A user asks for recommendations for a trip to Kyoto within a specified budget. The interaction model determines that additional information is required and emits a special token called DELEGATE. That token forwards the request to the background model.
While the background component performs the search, the conversational model can acknowledge the request and maintain the interaction. Once the result becomes available, the information is inserted into the conversation and used to produce a more detailed answer. The example involves a web search taking 7.1 seconds. The architecture does not make that search instantaneous. Instead, it prevents the entire spoken interaction from becoming silent while the task is running.
This separation may be valuable for voice agents that need to access tools, retrieve information or perform complex operations. Maintaining a natural conversation and solving a difficult problem do not necessarily require the same processing schedule.
Audio, text and actions are generated together
At the center of Shizuku-Duplex is a Transformer built around a language model. Incoming audio passes through a streaming encoder that extracts features from the user's speech. The interaction model processes those features alongside information from its previous cycle. It then produces several kinds of output.
Audio tokens are decoded into speech. A text component prepares verbal content slightly before the corresponding audio. The researchers call this intermediate text an Inner Monologue. It is an internal representation used during generation, not evidence of a complete human-like thought process.
A separate action component can select motions associated with the character's expression and intent. This includes integration with Live2D animation systems. The resulting design connects voice production with the movements of a virtual character. That matters for Shizuku AI's broader ambition of creating animated companions capable of sustaining natural interactions.
Why the project focuses on a virtual companion
Shizuku AI is developing Shizuku, an AI character intended for ongoing conversation. The company is not solely trying to build a general-purpose assistant that retrieves information as efficiently as possible. It wants the character's spoken responses, timing and animation to feel coherent.
Small conversational behaviors are important in that context. A timely acknowledgment, a hesitation or an appropriate pause can change how an interaction feels. Linking those signals with animated motion may also improve the consistency of a virtual character's presentation.
However, a convincing presentation should not be confused with human understanding or consciousness. The model generates responses and behaviors through computational processes. Natural voice timing does not establish that the system experiences emotions or understands relationships in a human sense.
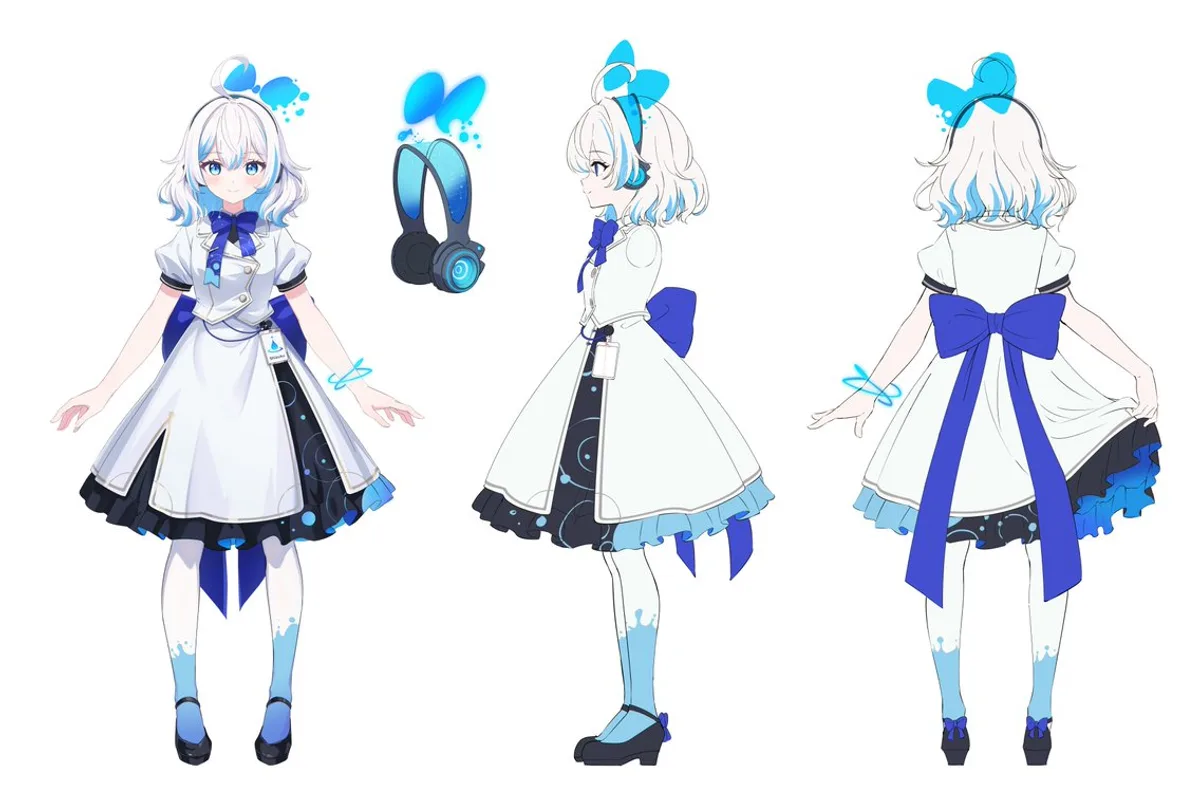
The Shizuku character illustrates the company's work on voice-driven animated companions. This is character artwork, not an image of the neural network architecture.
GPT-Live remains stronger on response quality
Shizuku AI's comparison shows a different picture when conversational timing is separated from response content. On Japanese casual conversation, Shizuku-Duplex scored 6.5 out of 10 for relevance. GPT-Live-1 scored 8.5. Naturalness of response content was rated 6.2 for Shizuku-Duplex and 7.6 for GPT-Live-1.
In multi-turn question answering, Shizuku-Duplex achieved 79% accuracy compared with 95% for GPT-Live-1. On questions requiring web lookup, the corresponding figures were 43% and 50%.
These results show why low latency should not be used as a substitute for answer quality. A model can manage the rhythm of a conversation convincingly while still providing weaker information. The developers describe Shizuku-Duplex as second only to GPT-Live among the full-duplex models they tested for response quality.
That assessment depends on their evaluation methodology. The researchers constructed Japanese conversational tests based on existing benchmark designs. They used automatic transcription and Claude Opus 5.5 as a judge for some content metrics. The results have not been independently reproduced across the full set of tasks.
The benchmark therefore supports a narrower conclusion than a universal market ranking. Shizuku-Duplex performed well under the team's selected conditions, particularly in conversational timing, while GPT-Live remained ahead on several measures of response content.
Long conversations require automatic context compression
Another challenge comes from extended conversations. A full-duplex system continuously processes the interaction, including periods of silence. Its context can therefore grow rapidly. As the accumulated information becomes larger, maintaining consistent responses becomes more difficult.
Shizuku-Duplex uses an automatic context-compaction mechanism. Approximately every five minutes, the system summarizes earlier conversation material and reconstructs its working context. The transition is designed to happen without interrupting the spoken exchange.
This can reduce the computational burden associated with retaining a continuously expanding history. However, compression creates its own trade-offs. A summary necessarily selects which information to preserve. Details that later become relevant may be lost or simplified. The researchers do not establish that the mechanism provides perfect memory across conversations of arbitrary duration.
It should be understood as a practical technique for maintaining longer interactions, rather than a complete solution to conversational memory.
What is actually available after the announcement?
The November 8 publication provides a technical explanation and several recorded demonstrations of Shizuku-Duplex. The research team has demonstrated the system with the Shizuku character's voice and persona. However, the article does not establish general availability of a standalone commercial product.
It does not confirm an openly accessible API, downloadable production model weights or a public pricing structure. The model should therefore be described as demonstrated and technically documented rather than universally available to developers.
Shizuku AI plans further improvements to its conversation capabilities. The researchers also mention future visual input and support for additional languages. Those features are planned areas of development rather than confirmed capabilities of the described Japanese model.
Natural conversation requires more than fast inference
Shizuku-Duplex is an interesting demonstration of the direction voice AI is taking. The underlying challenge is not only how quickly a system can generate words. It is whether the system can recognize when to respond, when to continue and when another speaker needs control of the conversation.
The 80 ms processing cycle contributes to that goal by supporting continuous listening and output. The reported 570 ms median response delay and the interruption tests suggest competitive conversational responsiveness.
But the high rate of unwanted responses to background speech reveals a serious remaining weakness. Response accuracy also trails GPT-Live in several of the team's tests. For virtual companions and other always-available voice systems, those limitations are important. The technology must not merely sound natural when a conversation proceeds as expected. It must also behave appropriately when several people speak, requests are ambiguous or a difficult task takes time.
Shizuku-Duplex shows meaningful progress toward that experience in Japanese. Its next milestones will include improving response reliability, reducing false interruptions and providing enough technical access for independent testing. The central innovation is not an AI that answers every question in 80 milliseconds. It is an architecture designed to keep listening throughout the conversation, making the interaction itself more continuous.